URL Encoder Spell Mistake: The Complete Guide to Fixing Encoding Errors
You type something into a search box. You hit enter. Instead of results, you get a broken page or a strange error. Most people call this a “url encoder spell mistake.” But it’s rarely a spelling problem. It’s almost always a URL encoder mistake hiding inside a web address.
This guide walks you through the whole picture. You’ll learn how URL encoding and URL decoding actually work, why encoding errors happen, and how they quietly hurt your SEO performance and user experience. We’ll also cover real fixes you can use today, whether you’re building a web application, debugging a REST API, or just trying to understand why a link won’t open.
What Is a URL Encoder Spell Mistake?
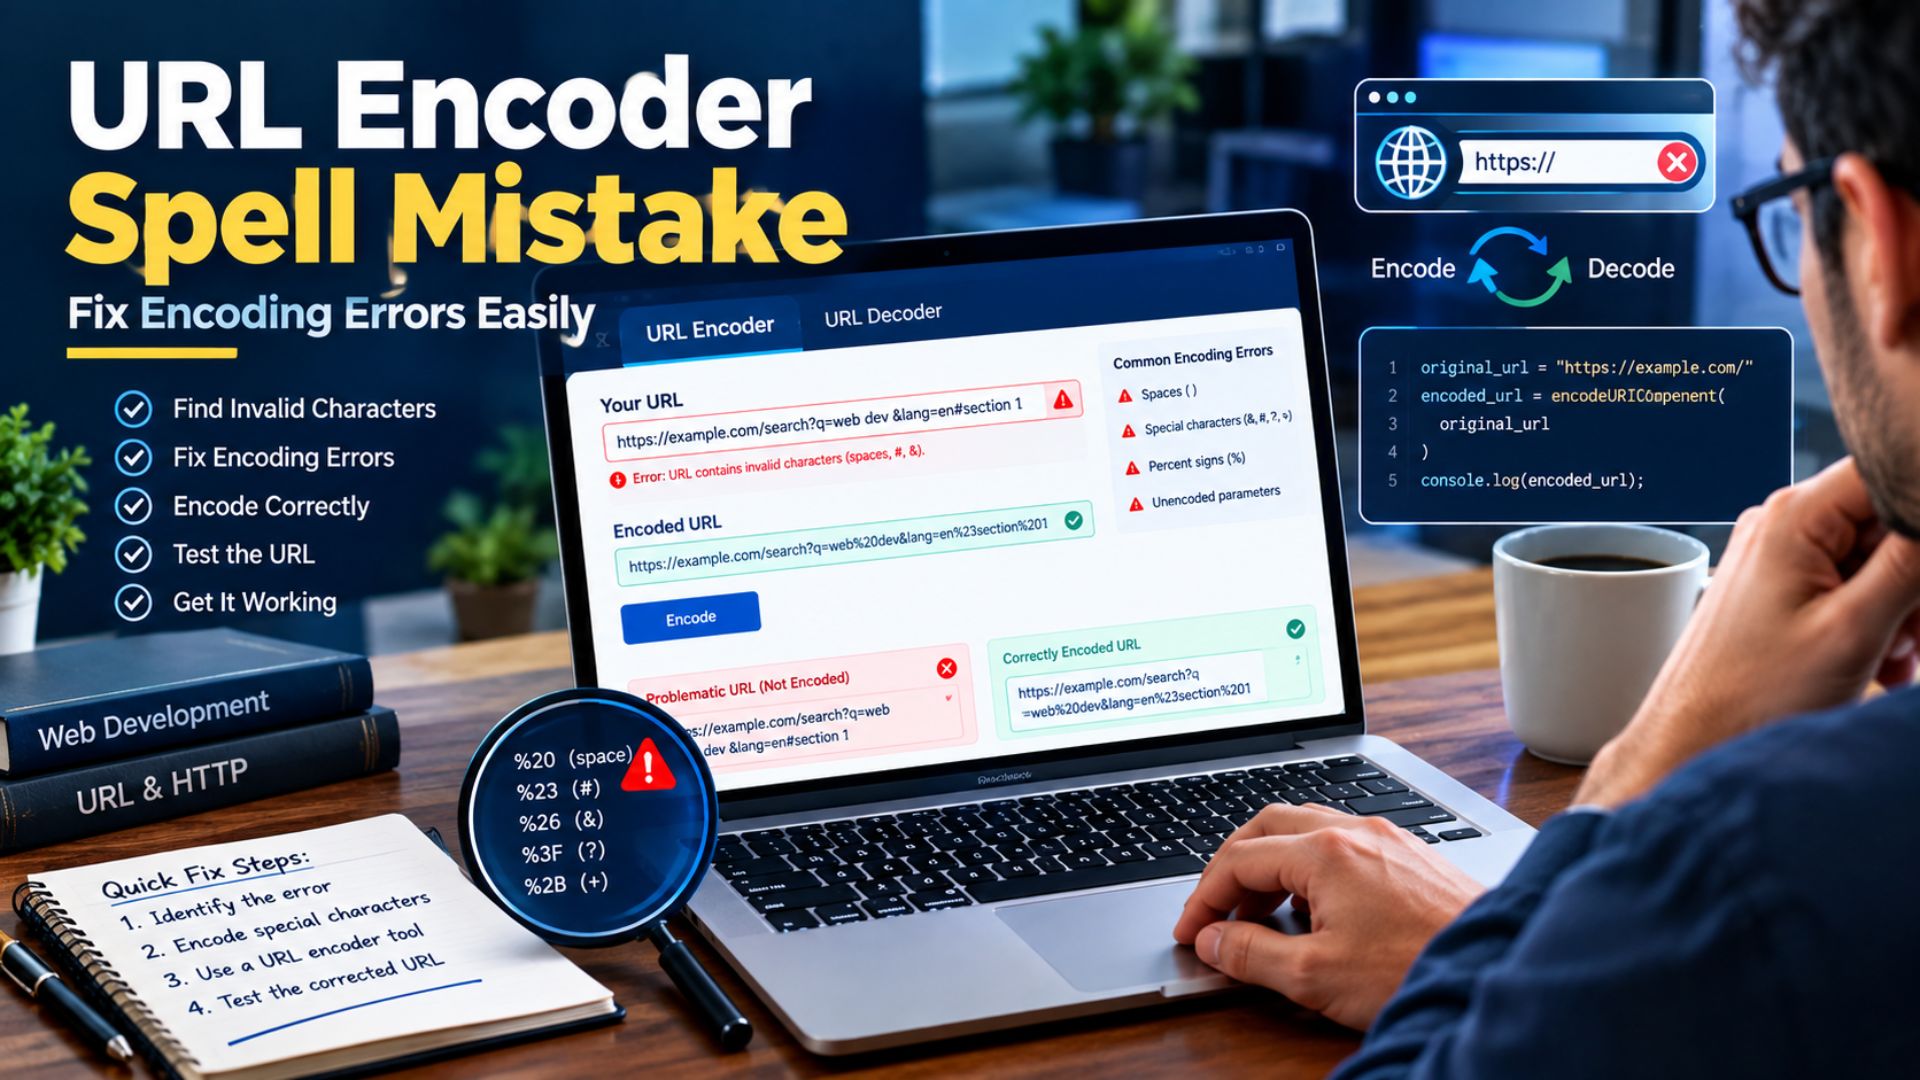
A url encoder spell mistake almost never means someone typed a word wrong. It means a character inside a URL got converted the wrong way. This includes incorrect character conversion, missing percent symbols, invalid encoded values, and wrong character sets. People search for url encoder spellmistake or url decoder spellmistake because their link, form, or API call stopped working, and they don’t know why.
Here’s a simple example. A space in a URL should become %20. That’s correct URL encoding. If the tool used instead produces %2World, that’s incorrect URL encoding, and the malformed URL won’t work the way you expect. This mix-up between a real typo and a broken encoding process is where most confusion starts.
Read More About: CNLawBlog Review 2026: Is It a Trusted Legal Information Source?
Why Correct URL Encoding Matters in Modern Web Systems
Every time you click a link, submit a form, or load a page, your web browser and the web server exchange data through an HTTP request. That data has to travel in a URL-safe format, or things break. Correct URL encoding keeps that exchange clean. Without it, special characters confuse the application server, and HTTP status codes like 400 or 500 start showing up where you don’t want them.
Think about it like mailing a package. You don’t just toss loose items in a box. You wrap them so they survive the trip. URL encoding does the same job for query parameters and form submissions. It protects data integrity as information moves between the client and the backend, across cloud applications, payment gateways, and content management systems that all depend on stable URL architecture.
Understanding How URL Encoding Works
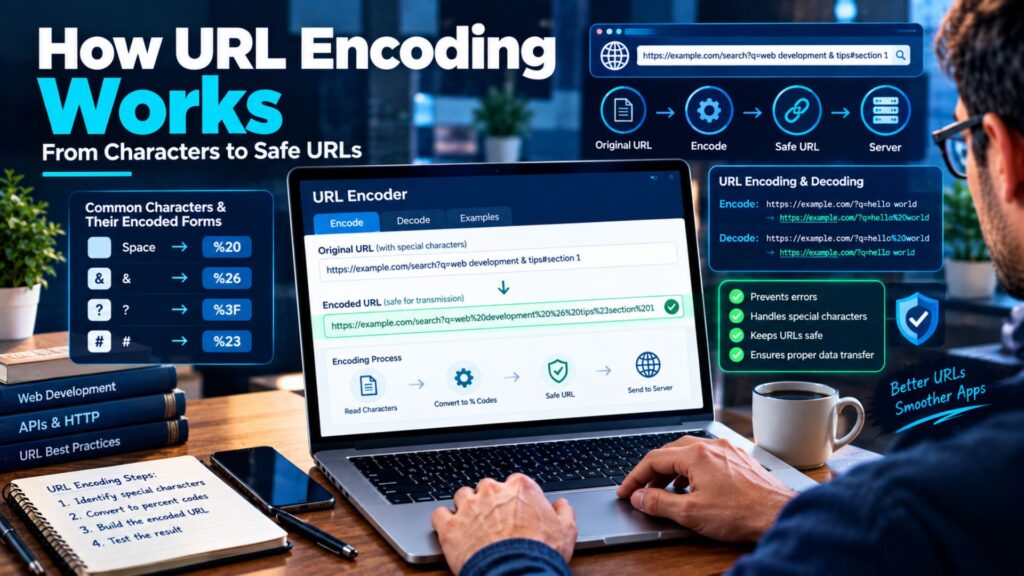
The URL Encoding Process
The URL encoding process follows a clear path. You type something into a search box or a form field. Your browser encodes it. It becomes part of an HTTP request. The server receives it, decodes it, and your application processes the result. Each step depends on the last one working correctly.
Here’s a plain example: red shoes & socks becomes red%20shoes%20%26%20socks once encoded. The decoded values on the server side turn back into readable text. This flow happens behind the scenes on almost every website you visit, from e-commerce platforms to analytics platforms.
URL Encoding vs. URL Decoding
URL encoding and URL decoding are opposite jobs, and mixing them up causes real problems.
| Process | What It Does | When It Happens |
| URL Encoding | Converts characters into web-safe format | Before the request is sent |
| URL Decoding | Converts encoded values back to normal text | After the server receives the request |
A url decoder spellmistake usually happens when data gets decoded too early, or decoded more than once. Understanding this difference is step one in any real URL encoding troubleshooting work.
Most Common URL Encoding Mistakes
Some common URL encoding mistakes show up again and again, no matter the platform. They’re rarely exotic. They’re usually small, repeatable slips in how reserved characters get handled.
Spaces Encoded Incorrectly
Spaces encoded incorrectly are probably the single most common issue you’ll run into. example.com/search?q=red shoes should read example.com/search?q=red%20shoes. Leaving the space raw can confuse server requests and split your query string in unexpected places.
Special Characters Left Unencoded
Special characters left unencoded, like &, ?, %, and =, can break a URL’s structure entirely. These are called reserved characters for a reason. They carry special meaning inside a URL, so leaving them raw creates broken URL parameters.
Invalid Percent Sequences
Invalid percent sequences happen when percent encoding doesn’t follow the rule of two hex digits. %20 is correct. %2 on its own is not, and it triggers encoding-related syntax errors the moment a server tries to read it.
Misspelled or Incorrect Encoded Values
Misspelled encoded values often come from someone typing an encoded value by hand instead of using a real function. %2G is a good example. Since G isn’t valid hex, this is invalid URL encoding, full stop.
Broken Query Parameters
Broken query parameters usually trace back to unencoded spaces or ampersands. ?name=John&city=New York should be ?name=John&city=New%20York. Get this wrong, and your query parameters stop matching what your backend expects.
Broken UTF-8 Characters
Not every problem is about symbols like & or %. UTF-8 character encoding issues show up when a name like “José” turns into “José.” This kind of character corruption is especially common on multilingual content and international websites, where Unicode text needs consistent handling across the whole stack.
Double Encoding and Recursive Encoding Errors
Double URL encoding is one of the sneakier problems in this whole topic. It happens through a repeated encoding process, often without anyone noticing until something visibly breaks downstream.
Multiple systems touching the same URL is usually the root cause. Middleware, frontend frameworks, and backend frameworks can all try to encode the same value, layering multiple encoding processes on top of each other and corrupting the original data.
What Double Encoding Looks Like
Start with hello world. First pass: hello%20world. Second pass: hello%2520world. Notice what happened: the % sign itself got encoded into %25. That’s recursive encoding in action, and it’s a classic encoding mistake that trips up even experienced developers.
Signs of Double Encoding
Watch your server logs and network traffic for a few tells.
| Sign | What It Usually Means |
| Repeated %25 in a URL | The % character got encoded again |
| Broken redirects | A redirect URL was encoded more than once |
| Garbled API responses | An API decoded the wrong layer |
| Search results that don’t match input | The query string got mangled before reaching the app |
How to Fix Double Encoding
Fixing this comes down to ownership. Decide once, clearly, which layer of your application workflow handles encoding, and make every other layer trust that decision. Document the rule so future coding standards don’t drift back into the same trap.
Real-World URL Encoding Error Examples
Theory only goes so far. Here’s where URL encoding error examples actually cost businesses money and traffic.
Spaces Inside Search Queries
A search query failure often starts small. A user searches “best laptops” and it works fine. They search “best gaming laptops” with a trailing space, and suddenly the search box returns nothing, because the unencoded space split the request parameters.
Ampersands Breaking Parameters
An ampersand left raw inside a value can split a query string into pieces the server never intended. “Best laptops & accessories” without encoding turns one search term into two separate, broken URL parameters.
Search Query Failures
Beyond spaces and ampersands, mixed special characters in user input cause a wider category of search request failures. Quotes, slashes, and percent signs typed directly into a form field are common offenders.
Broken Redirects
A broken redirect sends visitors somewhere they never meant to go. If a redirect URL carries an unencoded parameter, the destination page can load with missing or scrambled data, hurting both user experience and trust.
File Download Errors
A file download error often comes from a filename with spaces or symbols in it. “Q3 Report Final.pdf” needs proper encoding, or the download link breaks the moment it leaves the server.
API Request Failures
An API request failure looks like a logic bug at first glance, but it’s frequently just a malformed URL. A missing encoding step in a REST API call can trigger an HTTP 400 Bad Request before your actual code even runs.
How URL Encoding Errors Affect SEO
Encoding errors affect SEO in ways that aren’t always obvious at first. They don’t just break a page. They quietly chip away at rankings over months.
Crawl Issues
Crawl issues happen when a search crawler can’t reliably access a malformed URL. If Googlebot hits enough broken links, it starts trusting your site’s URL architecture less, which can slow down indexing across your whole domain.
Duplicate URLs and Content
Duplicate URLs are a quiet but real risk. /page-name and /page%2Dname can sometimes get treated as separate pages, creating duplicate content issues that split your page authority between two URLs instead of consolidating it into one.
Indexing Problems
Indexing problems follow naturally from crawl issues. A URL the search index can’t parse correctly often just doesn’t make it in at all, no matter how good the content behind it is.
User Experience Issues
User experience damage is the most visible cost. A visitor who hits a broken link once might try again. A visitor who hits it twice usually leaves, and that drop in engagement can quietly affect organic traffic over time.
International SEO Risks
International SEO risks grow fast when UTF-8 consistency breaks down. Corrupted international characters in a URL can tank visibility in markets using Arabic, Chinese, Japanese, Spanish, or Hindi content, even when the rest of the page is solid.
URL Encoding Problems in APIs and Backend Systems
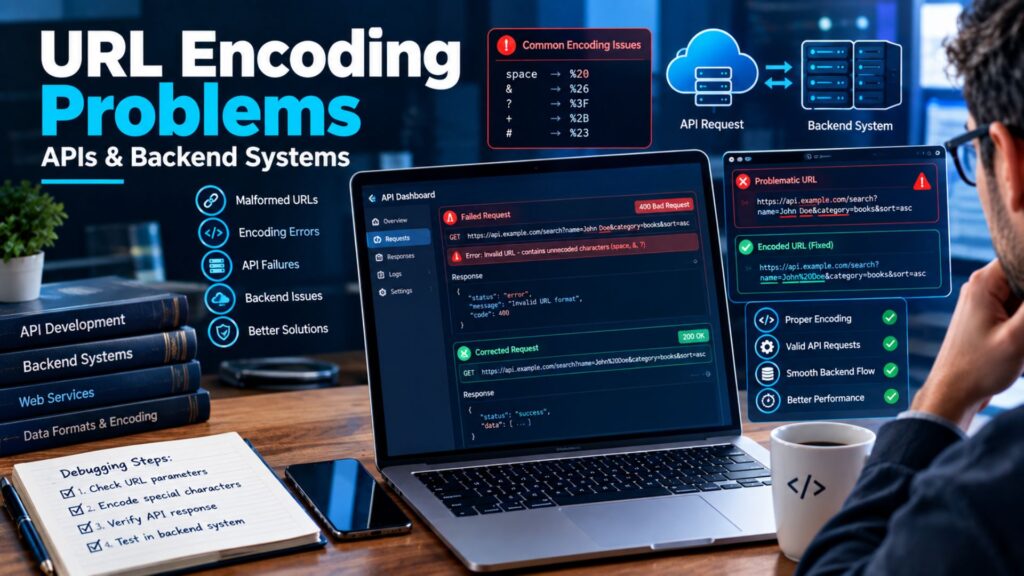
Common API Encoding Issues
API encoding issues show up as invalid query parameters, authentication failures, token corruption, and pagination errors. An API request like /api/search?q=laptops & tablets needs to become /api/search?q=laptops%20%26%20tablets, or the REST API may misread the ampersand as a parameter separator entirely.
Backend Parameter Handling
Backend responsibilities include validating, decoding, and processing incoming data safely. Good backend development never blindly trusts decoded user input. It checks, sanitizes, and only then passes the value deeper into the application logic.
Frontend vs. Backend Encoding Conflicts
Frontend Encoding Responsibilities
Frontend responsibilities usually cover form submissions, handling raw user input, and generating outbound URLs. A frontend framework typically encodes values right before sending them in a client request.
Backend Decoding Responsibilities
Backend responsibilities pick up from there: validation, decoding, processing, and storage. A well-built backend framework, whether that’s Django, Laravel, Spring Boot, or ASP.NET, expects encoded input and handles the decoding step in one predictable place.
Common Encoding Conflicts
Frontend vs backend encoding conflicts happen when both sides encode the same value. The frontend encodes it once. The backend encodes it again, not realizing the work was already done. The result is a classic double encoding error that’s easy to prevent with a clear, documented rule.
Why Manual URL Construction Causes Encoding Problems
Common Manual Construction Mistakes
Manual URL construction feels fast, but it’s risky. Simple string concatenation like “https://example.com?q=” + searchTerm works fine until searchTerm contains a space, an ampersand, or an emoji. Then it quietly becomes a malformed request waiting to happen.
Safer Alternatives to Manual URL Construction
The fix is straightforward: stop building URLs by hand. Every modern language ships trusted encoding functions built for exactly this job. Leaning on an encoding library instead of manual string work removes almost all of the guesswork, and it fits naturally into modern development workflows.
How to Diagnose URL Encoding Errors
Check Browser Developer Tools
Browser developer tools let you inspect the exact request your browser sent. The Network tab shows the raw request payload, which is often the fastest way to spot a bad encoded value.
Review Network Traffic
Network monitoring across your app can reveal patterns developer tools alone might miss, especially for issues that only show up under load or from certain devices.
Examine Server Logs
Server logs frequently capture the exact malformed URL that triggered an error, along with the HTTP status code it produced. This is often the quickest path to root cause.
Validate Encoded Values
Validate encoded values by comparing the original input against the encoded output. A quick manual check catches obvious mismatches before they reach production.
Search for Double Encoding
Search for double encoding by scanning logs for repeated %25 sequences. If you find them, you’re looking at a repeated encoding process somewhere in your stack.
Read More About: What Is Brumeblog com? Features, Topics, Benefits & Insights for 2026
Step-by-Step Process to Fix URL Encoding Problems
Identify the Problem URL
Start by pinning down exactly which URL is failing, and under what conditions. Vague reports (“search is broken”) need a specific, reproducible example before you can fix anything.
Locate Problem Characters
Scan the URL for spaces, reserved characters, and anything outside standard ASCII characters. These are almost always where the real issue hides.
Validate the Encoding
Confirm the percent-encoded characters follow the correct two-digit hex format. This single check catches a surprising number of bugs.
Test URL Decoding
Run the URL decoding process on the value and confirm it returns exactly what you expect. If it doesn’t, you’ve found your encoding mistake.
Test Across Browsers and Environments
Cross-platform behavior and browser compatibility can vary more than people expect. Test the same URL across a few browsers and devices before calling the fix complete.
Monitor the Production System
Production monitoring should continue after deployment. Production systems evolve, and new third-party integrations can reintroduce encoding bugs you already fixed once.
Programming Language Examples for Safe URL Encoding
Safe URL encoding looks a little different in every language, but the goal is always the same: never build URLs by hand.
| Language | Function | Example |
| JavaScript | encodeURIComponent() | encodeURIComponent(“red shoes & socks”) |
| PHP | urlencode() | urlencode(“red shoes & socks”) |
| Python | urllib.parse.quote() | urllib.parse.quote(“red shoes & socks”) |
| Java | URLEncoder.encode() | URLEncoder.encode(text, “UTF-8”) |
| C# | HttpUtility.UrlEncode() | HttpUtility.UrlEncode(text) |
Each of these functions handles character sets, hexadecimal value conversion, and reserved characters correctly, out of the box. You can read more in the official docs, including MDN’s encodeURIComponent reference and Python’s urllib.parse documentation.
Security Risks of Improper URL Encoding
Input Validation Risks
Weak input validation paired with poor encoding opens the door to real security vulnerabilities. Attackers look for exactly this kind of gap when probing a web application.
Parameter Manipulation Risks
Parameter tampering, open redirects, and data leakage all become easier when URL parameters aren’t validated and encoded properly. Session manipulation is another risk that grows when tokens pass through unvalidated URLs.
Why Encoding Alone Does Not Replace Validation
According to the OWASP Foundation, most injection-related security vulnerabilities stem from unvalidated input, not encoding alone. Encoding is one layer of defense in depth, not a replacement for real input validation in secure web applications.
Best Practices to Prevent URL Encoder Spell Mistakes
Use Standard Encoding Functions
Always reach for trusted encoding functions instead of manual encoding. This single habit prevents most common encoding errors before they ever happen.
Standardize Character Encoding
Standardized UTF-8 across your entire stack, from frontend to database, keeps multilingual content consistent and readable everywhere.
Validate Input
Check user input at the point of entry, not just before it hits the database. Early validation catches problems while they’re still cheap to fix.
Test Edge Cases
Edge-case testing should cover emoji, accented letters, long strings, and mixed scripts, not just plain English text.
Document Encoding Rules
Written encoding rules save future developers from repeating the same encoding conflicts your team already solved once.
Automate Encoding Tests
Automated testing frameworks catch regressions before they reach a production environment, which is far cheaper than catching them after launch.
Tools for Testing and Validating URL Encoding
A handful of URL validation tools cover most of what you’ll need day to day.
| Tool Type | Purpose |
| URL Encoders / URL Decoders | Convert text to and from web-safe format |
| Browser Developer Tools | Inspect raw requests and responses |
| API Testing Tools | Validate real API requests end to end |
| Server Log Analyzers | Spot malformed URLs at scale |
Reliable references worth bookmarking include MDN Web Docs, Postman, and the W3C.
URL Encoding Checklist for Developers
Development Stage
Use URL-safe functions from day one, enable UTF-8 everywhere, and configure basic input validation before writing feature logic.
Testing Stage
Test special characters, verify international characters, and validate every API request path before merging code.
Deployment Stage
Check redirects, review canonical URLs, and confirm error logs are actively monitored right after launch.
Maintenance Stage
Schedule regular audits, keep your encoding library updated, and repeat security testing as your app grows.
Frequently Asked Questions
What is a URL encoder spell mistake?
It’s usually a mislabeled encoding mistake, not a spelling error, caused by bad percent encoding or a malformed URL.
How do I fix invalid URL encoding?
Find the problem character, apply correct percent encoding, and test the result with a trusted encoding function.
What causes double URL encoding?
Double encoding happens when the same value passes through more than one encoding process without anyone checking first.
Does URL encoding affect SEO?
Yes. It can cause crawl issues, duplicate URLs, indexing problems, and lost organic traffic.
Why do special characters break URLs?
Reserved characters carry structural meaning inside a URL, so leaving them unencoded confuses both browsers and servers.
Should spaces be encoded as %20 or +?
%20 is the safer default for a URL path. + is a query-string convention that doesn’t belong in every context, so %20 is usually the right call.
Conclusion
A url encoder spell mistake almost always comes down to one thing: a character that never got encoded the right way. Once you understand the difference between URL encoding and URL decoding, spot the common failure patterns, and lean on trusted encoding functions instead of manual string work, most of these problems disappear.
Keep your UTF-8 consistency tight, validate every piece of user input, and check your server logs now and then for repeated %25. Do that, and you’ll catch most encoding mistakes long before they touch your rankings or your users.